Batch inference API
for your AI model
Optimized for cost and scale, with integrations to your existing data systems.
Deploy your model in our cloud or yours.
"We are very impressed with Nyckel's API-based hosting approach. It was simple to turn our idea into a reality."
Turn your custom model
into an API endpoint
We turn your model into a simple API endpoint, with integrations to common data platforms. Leave the heavy lifting of GPU management, cost optimization, scaling, and failure handling to us.

Hyper optimized for
cost and scale
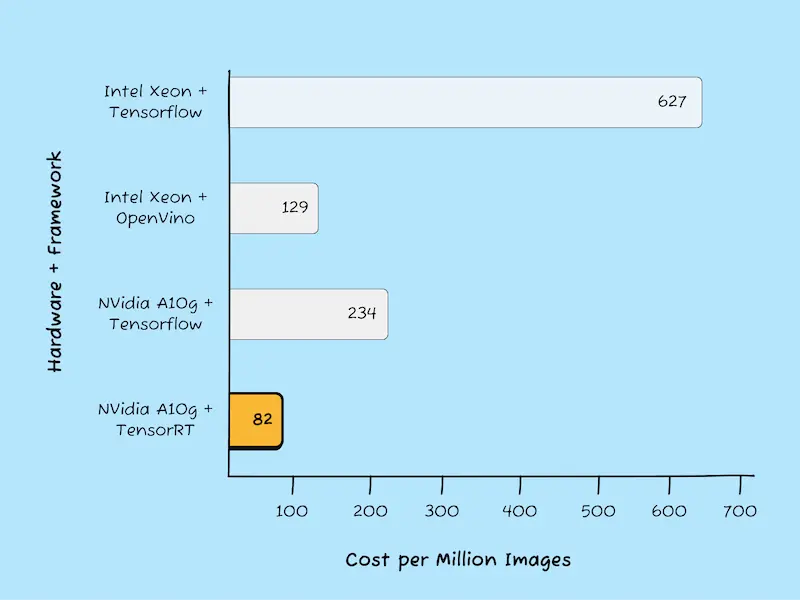
We optimize your model and hardware choice for cost per inference, then deploy close to your data to eliminate insidious data transfer fees. Process petabytes of data with clear per-inference pricing and no infrastructure headaches.
Predictable and simple
pricing
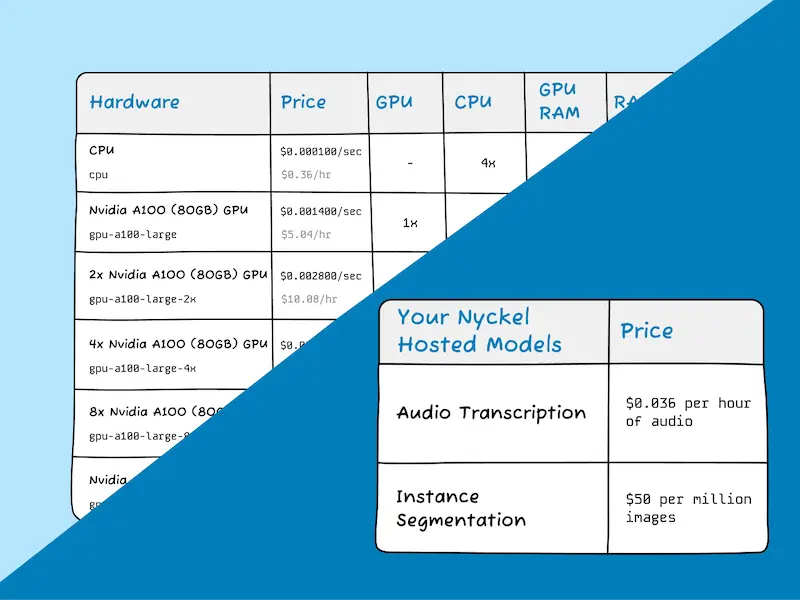
Tired of the guesswork around per-second GPU pricing? We price per inference unit so you know exactly how much you're going to pay.
Flexible
deployment options
Deploy your model on our secure infrastructure in any AWS, GCP, or Azure region. Or deploy in your cloud so your data never leaves your network.
Pricing
Pricing is tailored to your specific model. See some examples below.
We are typically 2-10x cheaper than alternatives.
| Model | Use | Price | Comparison |
|---|---|---|---|
| Whisper-V3-Large | Audio transcription | $0.036 per hour of audio | 10x cheaper than OpenAI |
| MaskRCNN | Image segmentation | $0.052 per 1k images | 3x cheaper than Pytorch on GPU |
| FasterRCNN | Image object detection | $0.048 per 1k images | 3x cheaper than Pytorch on GPU |
| Multilingual-e5-large | Text embeddings | $0.05 per 1M tokens | 2x cheaper than DeepInfra API |
Get a quote
Reach out to learn more and get a quote for your custom model.